


2025 Valid 010-160 Dumps for Helping Passing Lpi Exam!
Download Free Lpi 010-160 Exam Questions & Answer
The Linux Essentials Certificate Exam, version 1.6, is administered by the Linux Professional Institute (LPI), a non-profit organization that aims to promote and advance Linux and open source software. 010-160 exam is available in multiple languages and can be taken at any Pearson VUE testing center worldwide. Upon successful completion of the exam, candidates will receive the Linux Essentials Certificate, which is a valuable credential that demonstrates their knowledge and proficiency in Linux.
One of the key benefits of the Lpi 010-160 exam is that it is vendor-neutral, meaning that it is not specific to any particular Linux distribution. This makes it an excellent choice for individuals who are interested in pursuing a career in Linux or open source technology, regardless of which distribution they plan to work with. Additionally, the exam is designed to be accessible to individuals with a range of backgrounds and skill levels, making it an excellent choice for both beginners and experienced professionals.
NEW QUESTION # 34
What is true about thedmesgcommand? (Choose two correct answers.)
- A. It traces the execution of a command and shows each step the program carries out.
- B. It displays the content of the Linux kernel's ring buffer.
- C. It sends messages to the command lines of all current user sessions.
- D. It immediately outputs all new messages written to the system journal.
- E. It might not display older information because it was overwritten by newer information.
Answer: B,E
NEW QUESTION # 35
What is defined by a Free Software license?
- A. Details of the technical documentation each contributor has to provide.
- B. A complete list of libraries required to compile the licensed software.
- C. The programming languages which may be used to extend the licensed program.
- D. Limits on the purposes for which the licensed software may be used.
- E. Conditions for modifying and distributing the licensed software.
Answer: E
Explanation:
Explanation
A free software license is a notice that grants the recipient of a piece of software extensive rights to modify and redistribute that software. These actions are usually prohibited by copyright law, but the rights-holder (usually the author) of a piece of software can remove these restrictions by accompanying the software with a software license which grants the recipient these rights. Software using such a license is free software (or free and open-source software) as conferred by the copyright holder. Free software licenses grant users the freedom to use it for any purpose, study and change the source code and copy and redistribute the software with or without modifications. Free software must come with source code or provide access to it, while the freedom to redistribute includes the right to give away copies gratis as well as sell copies1 References: 1: Free-software license - Wikipedia
NEW QUESTION # 36
What is the UID of the user root?
- A. 0
- B. 1
- C. 2
- D. 3
- E. 4
Answer: D
Explanation:
Explanation/Reference:
NEW QUESTION # 37
What information can be displayed by top?
- A. User accounts, ordered by the number of files.
- B. User accounts, ordered by the number of logins.
- C. User groups, ordered by the number of members.
- D. Running processes, ordered by CPU or RAM consumption.
- E. Existing files, ordered by their size.
Answer: D
Explanation:
The top command is a Linux command that shows the running processes on the system. It provides a dynamic real-time view of the system performance and resource usage. The top command can display various information about the processes, such as their process ID, user, priority, state, CPU and memory usage, command name, and more. The top command can also sort the processes by different criteria, such as CPU or RAM consumption, by using the interactive commands. The top command is useful for monitoring the system load and identifying the processes that are consuming the most resources. Reference:
Linux Essentials Topic 104: The Linux Operating System, section 104.3: Basic features and commands of the Linux standard shells.
Linux Essentials Topic 106: Security and File Permissions, section 106.4: Monitor and manage Linux processes.
NEW QUESTION # 38
Which of the following types of bus can connect hard disk drives with the motherboard?
- A. The SATA bus
- B. The Auto bus
- C. The RAM bus
- D. The CPU bus
- E. The NUMA bus
Answer: A
Explanation:
Explanation
A bus is a communication system that transfers data between components inside a computer or between computers. There are different types of buses that serve different purposes. The RAM bus connects the CPU with the main memory, the NUMA bus connects multiple processors in a multiprocessor system, the CPU bus connects the CPU with other components on the motherboard, and the Auto bus is a fictional bus that can transform into a robot. The SATA bus is the correct answer because it is a type of bus that can connect hard disk drives with the motherboard. SATA stands for Serial Advanced Technology Attachment and it is a standard interface for connecting storage devices such as hard disk drives, solid state drives, and optical drives.
SATA offers faster data transfer rates, lower power consumption, and improved cable management compared to older interfaces such as IDE and SCSI. References: : [Bus (computing)] : [Transformers: Robots in Disguise (2015 TV series)] : [Serial ATA]3) : [SATA vs. IDE: What's the Difference?]
NEW QUESTION # 39
What is the purpose of the PATH environment variable?
- A. It indicates the location of the default shell to be used when a user logs in.
- B. It contains the absolute path to the current directory.
- C. It allows the execution of commands without the need to know the location of the executable.
- D. It specifies the location of a user's home directory.
- E. It increases security by preventing commands from running in certain locations.
Answer: C
NEW QUESTION # 40
When typing a long command line at the shell, what single character can be used to split a command across multiple lines?
Answer:
Explanation:
\
NEW QUESTION # 41
Which of the following statements regarding Linux hardware drivers is correct?
- A. Drivers are not used by Linux because the BIOS handles all access to hardware on behalf of Linux.
- B. Drivers are either compiled into the Linux kernel or are loaded as kernel modules.
- C. Drivers are regular Linux programs which have to be run by the user who wants to use a device.
- D. Drivers are stored on their devices and are copied by the Linux kernel when a new device is attached
- E. Drivers are downloaded from the vendor's driver repository when a new device is attached.
Answer: B
Explanation:
Linux hardware drivers are software components that enable the Linux kernel to communicate with various devices, such as keyboards, mice, printers, scanners, network cards, etc. Drivers are either compiled into the Linux kernel or are loaded as kernel modules. Kernel modules are pieces of code that can be loaded and unloaded into the kernel on demand. They extend the functionality of the kernel without requiring to rebuild or reboot the system. Drivers that are compiled into the kernel are always available, but they increase the size and complexity of the kernel. Drivers that are loaded as kernel modules are only available when needed, but they require a matching version of the kernel and the module. Linux supports a large number of hardware devices, thanks to the efforts of the open source community and some vendors who provide drivers for their products. However, some devices may not have a driver available for Linux, or may require a proprietary driver that is not included in the Linux distribution. In such cases, the user may need to install the driver manually from the vendor's website or from a third-party repository. Reference:
Linux Essentials - Linux Professional Institute (LPI), section 2.2.1
LPI Linux Essentials Study Guide: Exam 010 v1.6, 3rd Edition, chapter 3, page 67.
NEW QUESTION # 42
Running the command rm Downloads leads to the following error:
rm: cannot remove 'Downloads/': Is a directory
Which of the following commands can be used instead to remove Downloads, assuming Downloads is empty? (Choose two correct answers.)
- A. rem Downloads
- B. undir Downloads
- C. dir -r Downloads
- D. rm -r Downloads
- E. rmdir Downloads
Answer: D,E
Explanation:
To remove a directory, you need to use a command that can delete directories, not just files. The rm command can only remove files by default, unless you use the -r option, which stands for recursive. This option tells rm to delete the directory and all of its contents, including subdirectories and files. The rmdir command can also remove directories, but only if they are empty. If the directory contains any files or subdirectories, rmdir will fail and display an error message. Therefore, the correct commands to remove Downloads, assuming it is empty, are rmdir Downloads and rm -r Downloads. The other commands are either invalid or do not work on directories. Reference:
Linux Essentials - Linux Professional Institute (LPI), section 2.3.1
LPI Linux Essentials Study Guide: Exam 010 v1.6, 3rd Edition, chapter 4, page 93.
NEW QUESTION # 43
Where is the operating system of a Raspberry Pi stored?
- A. On rewritable flash storage which is built into the Raspberry Pi.
- B. On a read only partition on the Raspberry Pi's firmware, next to the BIOS.
- C. On a removable SD card which is put into the Raspberry Pi.
- D. On a Linux extension module connected to the Raspberry Pi's GPIO pins.
- E. On the master device attached to the Raspberry Pi's IDE bus.
Answer: C
Explanation:
Explanation
The Raspberry Pi uses an SD card (or microSD card for newer models) as its main storage device. This means that the operating system and any other files are stored on the SD card, which can be easily inserted or removed from the Raspberry Pi. The SD card also allows the user to switch between different operating systems by using different cards or partitions. The Raspberry Pi does not have any internal storage, such as a hard disk drive or a solid state drive, nor does it use any external devices, such as an IDE bus, a firmware partition, or a GPIO module, to store the operating system. References:
* Raspberry Pi OS - Raspberry Pi
* Choosing Storage for Raspberry Pi - Kingston Technology
* Beginner's Guide: How To Install a New OS on Raspberry Pi
NEW QUESTION # 44
A directory contains the following files: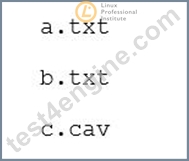
What would be the output of the following shell script?
for file in *.txt
- A. *.txt
- B. c.cav
- C. a b
- D. A. txt
- E. A.txt
Answer: D
Explanation:
b. txt
Explanation:
The shell script uses a for loop to iterate over the files that match the pattern *.txt in the current directory. The pattern *.txt means any file name that ends with .txt, regardless of the case. The loop body simply prints the value of the variable file, which holds the name of the current file in each iteration. Therefore, the output of the shell script would be the names of the files that end with .txt, one per line. In this case, the files are A.txt and b.txt, so the output would be:
A .txt b.txt
This corresponds to option E. The other options are incorrect for the following reasons:
Option A: *.txt is not the output of the shell script, but the pattern that the loop uses to match the files. The shell expands the pattern to the actual file names before executing the loop.
Option B: a and b are not the names of the files, but the first characters of the file names. The loop prints the whole file name, including the extension.
Option C: c.cav is not a file that matches the pattern *.txt, because it has a different extension. The loop ignores files that do not end with .txt.
Option D: A.txt is only one of the files that matches the pattern *.txt, but not the only one. The loop prints both A.txt and b.txt.
NEW QUESTION # 45
Which of the following tasks can the command passwd accomplish? (Choose two.)
- A. Create a new user account.
- B. Change a user's username.
- C. Change a user's password.
- D. Lock a user account.
- E. Create a new user group.
Answer: C,D
Explanation:
Explanation
The passwd command in Linux is used to change the password of a user account. A normal user can run passwd to change their own password, and a system administrator (the superuser) can use passwd to change another user's password, or define how that account's password can beused or changed1. The passwd command can also be used to lock or unlock a user account. Locking a user account means disabling the user's ability to log in to the system, while unlocking a user account means restoring the user's ability to log in. To lock a user account, the passwd command can be used with the -l option, followed by the username. To unlock a user account, the passwd command can be used with the -u option, followed by the username12. The passwd command cannot be used to change a user's username, create a new user account, or create a new user group. These tasks require different commands, such as usermod, useradd, orgroupadd345. References: 1:
Linux Passwd Command Help and Examples 2: Passwd command in Linux: 8 Practical Examples 3:
usermod(8) - Linux man page 4: useradd(8) - Linux man page 5: groupadd(8) - Linux man page
NEW QUESTION # 46
Which statements about the directory /etc/skel are correct? (Choose two.)
- A. The files from the directory are copied to the home directory of the new user when starting the system.
- B. The personal user settings of root are stored in this directory.
- C. The files from the directory are copied to the home directory of a new user when the account is created.
- D. The directory contains a default set of configuration files used by the useradd command.
- E. The directory contains the global settings for the Linux system.
Answer: C,D
Explanation:
Explanation
The /etc/skel directory is a skeleton directory that contains the default files and directories that are automatically copied to the home directory of a new user when the account is created by the useradd command12. The purpose of this directory is to provide a consistent and uniform environment for all new users and to save the system administrator's time and effort in configuring the user settings12. The /etc/skel directory can be customized by adding or removing files and directories as needed, depending on the desired default settings for the new users12.
The other options are incorrect because:
* A. The personal user settings of root are stored in this directory. This is not true, as the personal user settings of root are stored in the /root directory, which is the home directory of the root user3. The
/etc/skel directory does not affect the root user's settings, but only the settings of the new users created by the useradd command12.
* B. The files from the directory are copied to the home directory of the new user when starting the system. This is not true, as the files from the directory are copied to the home directory of the new user when the account is created, not when starting the system12. The copying process only happens once, when the useradd command is executed, and not every time the system is started12.
* E. The directory contains the global settings for the Linux system. This is not true, as the directory contains the default settings for the new users, not the global settings for theLinux system12. The global settings for the Linux system are usually stored in other directories under /etc, such as /etc/default,
/etc/sysconfig, /etc/init.d, etc4.
References:
* Understanding the /etc/skel directory in Linux - The Geek Diary
* /etc/skel directory in Linux - techPiezo
* Linux File System Hierarchy - /root directory - LinuxConfig.org
* Linux configuration: Understanding *.d directories in /etc | Enable Sysadmin
NEW QUESTION # 47
Which of the following devices represents a hard disk partition?
- A. /dev/sda/p2
- B. /dev/sda2
- C. /dev/part0
- D. /dev/ttyS0
- E. /dev/sata0
Answer: B
Explanation:
Explanation
The correct device name that represents a hard disk partition is /dev/sda2. This device name follows the Linux convention for naming hard disk devices and partitions. According to this convention123:
* The first part of the device name indicates the type of the device. For example, /dev/hd* for IDE drives,
/dev/sd* for SCSI, SATA, USB, or eSATA drives, /dev/nvme* for NVMe drives, etc.
* The second part of the device name indicates the order of the device as detected by the system. For example, /dev/sda is the first serial drive, /dev/sdb is the second serial drive, and so on.
* The third part of the device name indicates the number of the partition on the device. For example,
/dev/sda1 is the first partition on the first serial drive, /dev/sda2 is the second partition on the first serial drive, and so on.
Therefore, /dev/sda2 means the second partition on the first serial drive, which is a valid hard disk partition.
The other options are not valid hard disk partitions, because they do not follow the Linux convention. For example:
* /dev/ttyS0 is a serial port device, not a hard disk device4.
* /dev/sata0 is not a valid device name, because it does not specify the partition number. It should be something like /dev/sata0p1 or /dev/sata0p2, etc.
* /dev/part0 is not a valid device name, because it does not specify the device type or the partition number. It should be something like /dev/sdXp0 or /dev/hdXp0, etc.
* /dev/sda/p2 is not a valid device name, because it uses a slash (/) instead of a number to indicate the partition. It should be something like /dev/sda2 or /dev/sda3, etc.
References: 1: Hard drive/device partition naming convention in Linux - Unix & Linux Stack Exchange 2:
Hard drive partition naming convention in Linux - Ask Ubuntu 3: C.4. Device Names in Linux - Debian 4:
What is /dev/ttyS0? - Quora
NEW QUESTION # 48
Which of the following commands creates an archive filework.tarfrom the contents of the directory./ work/?
- A. tar -create work.tgz -content ./work/
- B. tar -cf work.tar ./work/
- C. tar work > work.tar
- D. tar work.tar < ./work/
- E. tar --new work.tar ./work/
Answer: B
Explanation:
Explanation
The correct command to create an archive file work.tar from the contents of the directory ./work/ is tar
-cf work.tar ./work/. This command uses the -c option to create a new archive, the -f option to specify the file name, and the ./work/ argument to indicate the source directory. The other commands are incorrect for various reasons:
* A. tar --new work.tar ./work/ is incorrect because there is no --new option in the tar command.
The correct option for creating a new archive is --create or -c.
* C. tar -create work.tgz -content ./work/ is incorrect because the -content option is not valid. The correct option for specifying the source files or directories is --files-from or -T. Also, the work.tgz file name implies compression, but the command does not use any compression option such as -z,
-j, or -J.
* D. tar work.tar < ./work/ is incorrect because the tar command does not accept input redirection from the standard input. The correct way to use the tar command is to provide the options and arguments after the command name.
* E. tar work > work.tar is incorrect because the tar command does not produce output redirection to the standard output. The correct way to use the tar command is to use the -f option to specify the output file name. References: : tar command in Linux with examples - GeeksforGeeks : tar Command in Linux With Examples | phoenixNAP KB
NEW QUESTION # 49
The file script.sh in the current directory contains the following content:
#!/bin/bash echo $MYVAR
The following commands are used to execute this script:
MYVAR=value
./script.sh
The result is an empty line instead of the content of the variable MYVAR. How should MYVAR be set in order to make script.sh display the content of MYVAR?
- A. !MYVAR=value
- B. $MYVAR=value
- C. MYVAR=value
- D. env MYVAR=value
- E. export MYVAR=value
Answer: E
Explanation:
Explanation
The reason why the script.sh does not display the content of the variable MYVAR is that the variable is not exported to the environment of the script. When a script is executed, it runs in a separate process that inherits the environment variables from the parent process, but not the shell variables. A shell variable is a variable that is defined and visible only in the current shell session, while an environment variable is a variable that is exported to the environment and visible to all processes that run in that environment1.
To make a shell variable an environment variable, we need to use the export command. The export command takes a shell variable name and adds it to the environment of the current shell and any subshells or processes that are created from it2. For example, to export the variable MYVAR with the value value, we can use:
export MYVAR=value
This will make the variable MYVAR available to the script.sh when it is executed, and the script will print the value of MYVAR as expected. Alternatively, we can also use the export command with the -n option to remove a variable from the environment, or with the -p option to list all the environment variables2.
The other options are not valid ways to set MYVAR as an environment variable. The !MYVAR=value option is not a valid syntax for setting a variable in bash. The env MYVAR=value option will run the env command with the MYVAR=value argument, which will print the environment variables with the addition of MYVAR=value, but it will not affect the current shell or the script.sh3. The MYVAR=value option will set MYVAR as a shell variable, but not as an environment variable, so it will not be visible to the script.sh1. The
$MYVAR=value option will try to set the variable whose name is the value of MYVAR to the value value, which is not what we want4. References:
* Linux Essentials Exam Objectives, Version 1.6, Topic 103.1, Weight 2
* Linux Essentials Certification Guide, Chapter 3, Page 51-52
* env(1) - Linux manual page
* Bash Variables - LinuxConfig.org
NEW QUESTION # 50
Reverse DNS assigns hostnames to IP addresses. How is the name of the IP address 198.51.100.165 stored on a DNS server?
- A. In the REV record forarpA.in-addr.198.51.100.165.
- B. In the PTR record for165.100.51.198.in-addr.arpA.
- C. In the RNAME record for198-51-100-165.rev.arpA.
- D. In the A record for165.100.51.198.ipv4.arpA.
- E. In the ARPA record for165.100.51.198.rev.
Answer: B
Explanation:
Explanation
Reverse DNS lookups query DNS servers for a PTR (pointer) record; if the server does not have a PTR record, it cannot resolve a reverse lookup. PTR records store IP addresses with their segments reversed, and they append ".in-addr.arpa" to that. For example, if a domain has an IP address of 192.0.2.1, the PTR record will store the domain's information under 1.2.0.192.in-addr.arpa. In IPv6, the latest version of the Internet Protocol, PTR records are stored within the ".ip6.arpa" domain instead of ".in-addr.arpa."1 Therefore, the name of the IP address 198.51.100.165 is stored in the PTR record for
165.100.51.198.in-addr.arpa. References: 1: Reverse DNS lookup - Wikipedia 1
NEW QUESTION # 51
How is a new Linux computing instance provisioned in an laaS cloud?
- A. The installation has to be prepared in a local virtual machine which is then copied to the cloud.
- B. After buying a Linux distribution, its vendor delivers it to a cloud instance.
- C. A provider-specific configuration file describing the desired installation is uploaded to the cloud provider.
- D. The standard Linux installer has to be run through a remote console.
- E. The cloud hosting organization provides a set of pre-prepared images of popular Linux distributions.
Answer: E
Explanation:
In an Infrastructure as a Service (IaaS) cloud, the provider offers virtualized computing resources such as servers, storage, and network over the internet. The user can provision and manage these resources according to their needs. One of the common ways to provision a new Linux computing instance in an IaaS cloud is to use a pre-prepared image of a Linux distribution provided by the cloud hosting organization. An image is a snapshot of a virtual machine that contains the operating system and other software components. The user can choose from a variety of images that suit their requirements and launch a new instance from the image. This way, the user does not have to install and configure the Linux operating system from scratch, which saves time and effort. Some examples of cloud hosting organizations that provide pre-prepared images of popular Linux distributions are Amazon Web Services (AWS), Microsoft Azure, Google Cloud Platform (GCP), and DigitalOcean. Reference: Linux Essentials - Topic 108: Cloud Computing and Linux Essentials - Topic 108: Cloud Computing - Exam Objectives
NEW QUESTION # 52
Which of the following examples shows the general structure of a for loop in a shell script?
- A. for *.txt ( echo $i )
- B. for ls *.txt exec {} \;
- C. foreach @{file} { echo $i
} - D. for file in *.txt do
echo $i done - E. for *.txt as file => echo $file
Answer: D
Explanation:
Explanation
The general structure of a for loop in a shell script is as follows12:
for variable in list do commands done
The variable is the name of a loop counter or iterator that takes on the values of the items in the list. The list can be a sequence of words, numbers, filenames, or the output of a command. The commands are the body of the loop that are executed for each value of the variable. The do and done keywords mark the beginning and the end of the loop body.
The option C. for file in *.txt do echo $i done follows this structure, with the variable being file, the list being
*.txt (which matches all the files with the .txt extension in the current directory), and the command being echo
$i (which prints the value of the variable i, which is presumably set somewhere else in the script).
The other options are incorrect because:
* A. for *.txt as file => echo $file uses an invalid syntax for a for loop. The as keyword is not part of the shell script syntax, and the => symbol is not a valid operator. The correct way to write this loop would be:
for file in *.txt do echo $file done
* B. for *.txt ( echo $i ) uses an invalid syntax for a for loop. The parentheses are not part of the shell script syntax, and the loop body is missing the do and done keywords. The correct way to write this loop would be:
for i in *.txt do echo $i done
* D. for ls *.txt exec {} ; uses an invalid syntax for a for loop. The ls command is not a valid variable name, and the exec {} ; is not a valid command. This looks like a mix of a for loop and a find command.
The correct way to write this loop would be:
for file in *.txt do exec $file done
* E. foreach @{file} { echo $i } uses an invalid syntax for a for loop. The foreach keyword is not part of the shell script syntax, and the @{file} and { echo $i } are not valid expressions. This looks like a mix of a for loop and a Perl syntax. The correct way to write this loop would be:
for file in * do echo $file done
References:
* Looping Statements | Shell Script - GeeksforGeeks
* How do I write a 'for' loop in Bash? - Stack Overflow
NEW QUESTION # 53
Which of the following commands are used to get information on the proper use of ls? (Choose two correct answers.)
- A. manual ls
- B. man ls
- C. usage ls
- D. info ls
- E. option ls
Answer: B,D
Explanation:
The commands man ls and info ls are used to get information on the proper use of ls. The man command displays the manual page for a given command, which contains a description, synopsis, options, examples, and other details. The info command displays the info page for a given command, which is similar to the manual page but may have more information and hyperlinks. The option ls, usage ls, and manual ls commands are not valid commands in Linux and will result in an error message. Reference:
Linux Essentials Exam Objectives, Version 1.6, Topic 103.1, Weight 2
Linux Essentials Certification Guide, Chapter 3, Page 51-52
Ls Command in Linux (List Files and Directories) | Linuxize
NEW QUESTION # 54
Which command copies the contents of the directory /etc/, including all sub-directories, to /root/?
- A. cp -r /etc/* /root
- B. copy /etc /root
- C. rcp /etc/* /root
- D. cp -v /etc/* /root
- E. cp -R /etc/*.* /root
Answer: A
Explanation:
The correct command to copy the contents of the directory /etc/, including all sub-directories, to /root/ is cp -r /etc/* /root. This command uses the cp command, which stands for copy, and is used to copy files and directories on Linux and Unix systems. The command also uses the following options and arguments123:
The -r option, which stands for recursive, and tells cp to copy all files and sub-directories of the source directory. Alternatively, the -R option can be used, which has the same effect as -r.
The /etc/* argument, which specifies the source directory and all its contents. The asterisk (*) is a wildcard character that matches any file or directory name. This argument tells cp to copy everything inside the /etc/ directory, but not the directory itself.
The /root argument, which specifies the destination directory. This argument tells cp to copy the source files and sub-directories to the /root/ directory.
The other options are incorrect because they use different commands or syntax that do not copy the contents of the directory /etc/, including all sub-directories, to /root/. For example:
Option A uses the copy command, which is not a valid Linux command. The correct command is cp.
Option C uses the -v option, which stands for verbose, and tells cp to print verbose output. This option does not affect the copying process, but only the output. It also does not include the -r or -R option, which is necessary to copy the sub-directories.
Option D uses the rcp command, which stands for remote copy, and is used to copy files between different hosts on a network. This command is not relevant for copying files on the same host.
Option E uses the -R option, which is correct, but also uses the . argument, which is incorrect. The dot (.) is a special character that matches any single character. This argument tells cp to copy only the files and directories that have a dot in their name, which may exclude some files and directories that do not have a dot.
NEW QUESTION # 55
When typing a long command line at the shell, whatsingle charactercan be used to split a command across multiple lines?
Answer:
Explanation:
Explanation
The backslash character () is used to escape the meaning of the next character in a command line. This means that the next character is treated as a literal character, not as a special character. For example, if you want to use a space in a file name, you can use a backslash before the space to prevent the shell from interpreting it as a separator. Similarly, if you want to split a long command line across multiple lines, you can use a backslash at the end of each line to tell the shell that the command is not finished yet. The shell will ignore the newline character and continue reading the next line as part of the same command.
For example, you can write:
ls -l/home/user/Documents
instead of:
ls -l /home/user/Documents
Both commands will produce the same output, but the first one is easier to read and type. References:
* Linux Essentials - Linux Professional Institute (LPI), section 2.1.2
* 2.1 Command Line Basics - Linux Professional Institute Certification Programs, slide 7.
NEW QUESTION # 56
......
To prepare for the exam, candidates can take advantage of the many resources available, such as study guides, practice exams, and online courses. The Linux Essentials certification exam is an excellent way to validate your knowledge and skills in Linux and open-source software and can open up many opportunities in the IT industry.
010-160 Exam Dumps For Certification Exam Preparation: https://troytec.test4engine.com/010-160-real-exam-questions.html